
Pilot block
Validate your own AI workloads on a pilot block, testing compute throughput, fabric and storage performance before committing to a larger deployment.
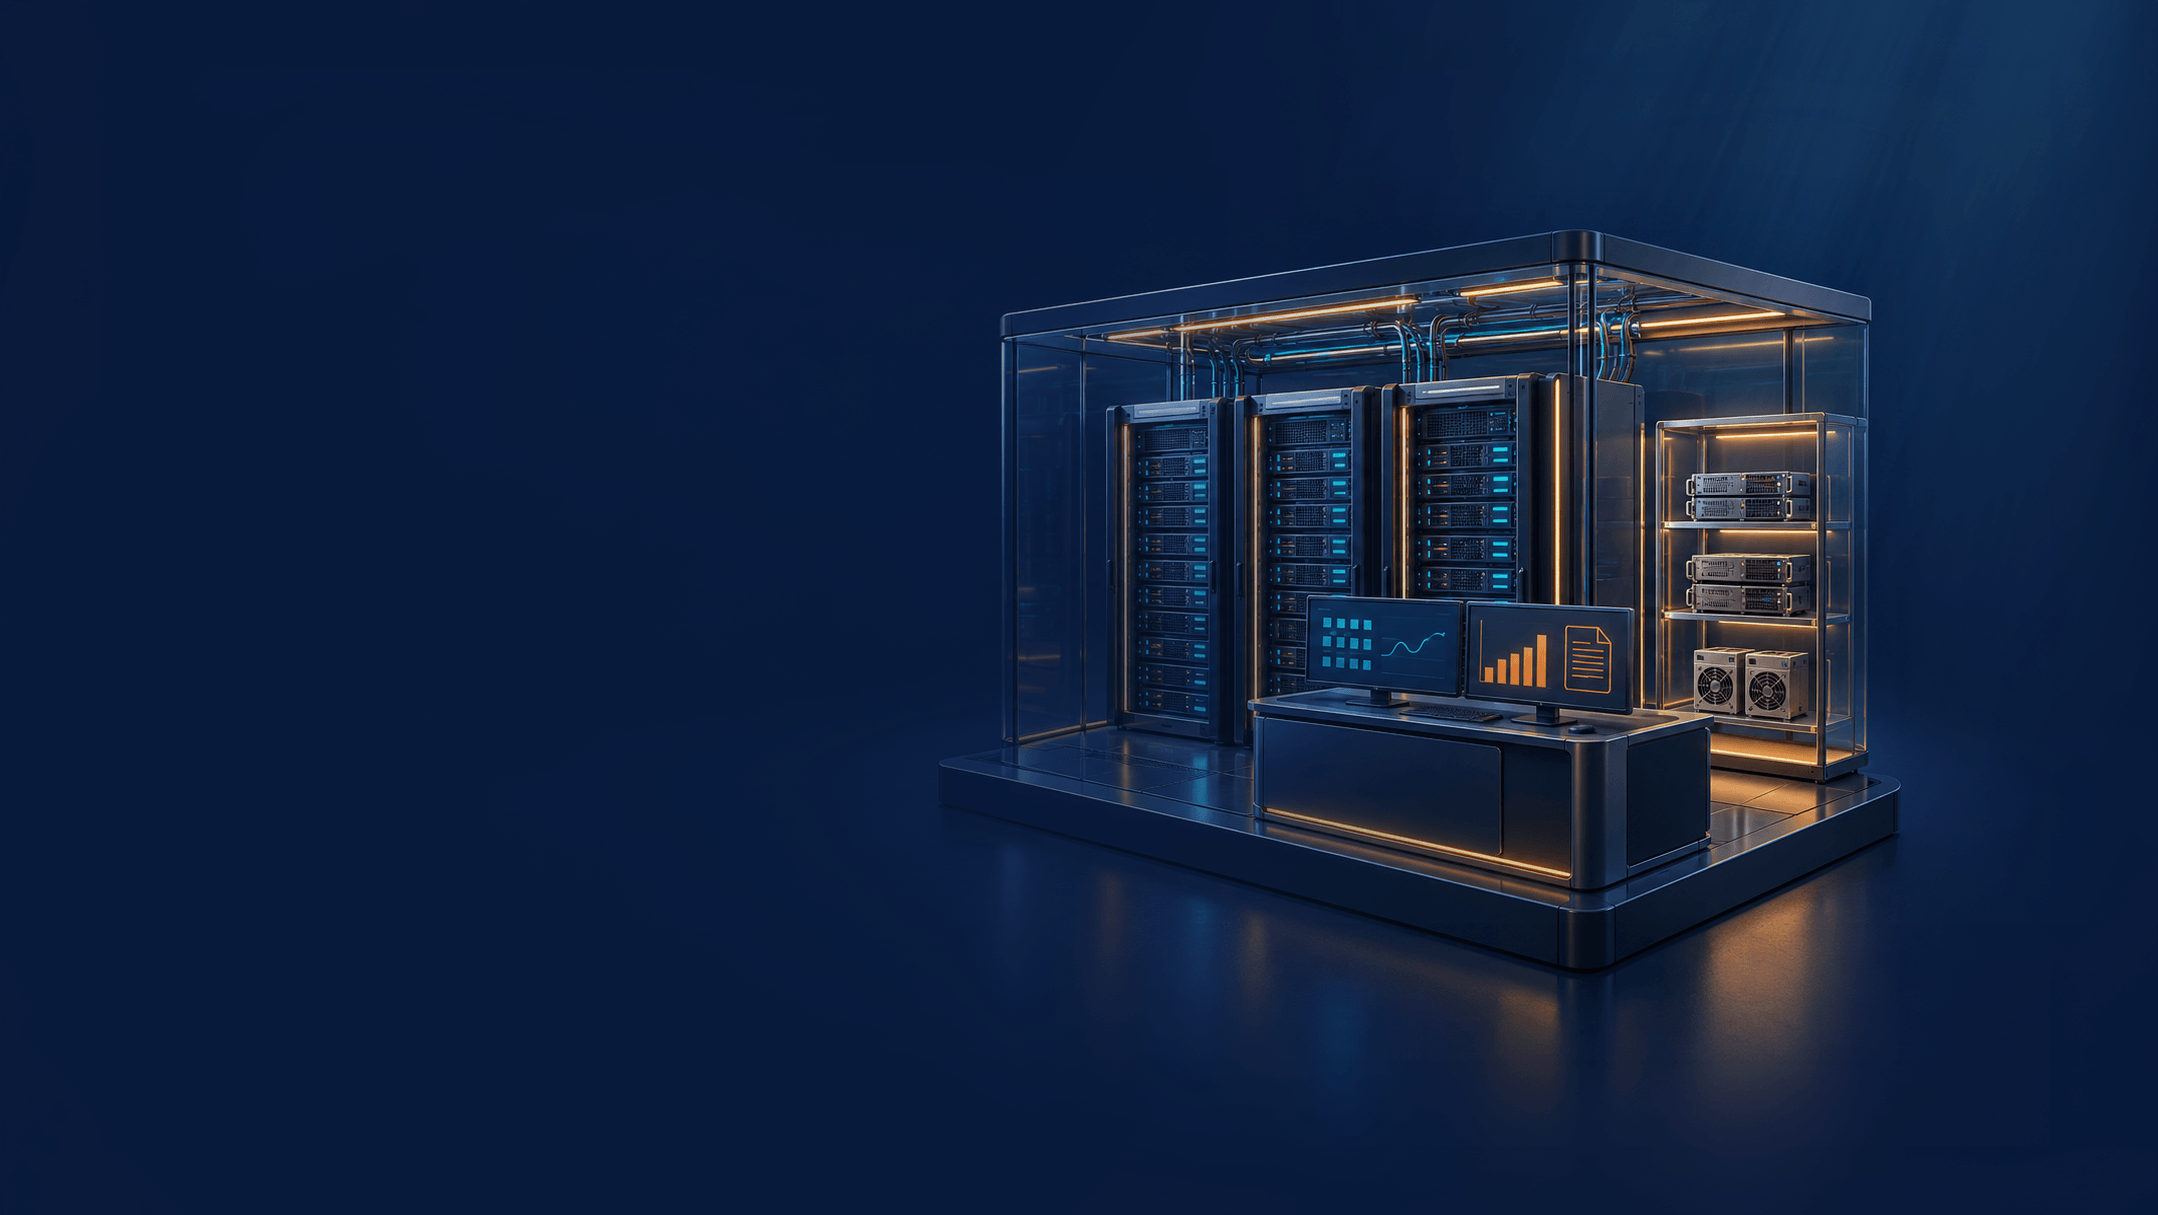
Build and run your ambitious AI workloads on dedicated B300 and GB300-class clusters, with power, liquid cooling, high-speed fabric, storage and cluster operations engineered as one under a single accountable delivery model.
Large-scale AI factory buildout underway in Sydney
NVIDIA B300 GPUsSuperPOD architecture · 17.83 PB of VAST Data storage
GPUsAcross international programmes in execution and acquisition
Operating mission-critical data centre infrastructure
Listed on NSE and BSEAudited financials and public disclosures
GPUs are one part of the engine. Every layer must be ready before the full cluster can run together.
Allocation and delivery dates must align with your training roadmap.
A site is only ready when power and cooling can support the cluster at the rack.
Cooling, fabric, storage and burn-in must work together before the first training run.
Failures, slow checkpoints and storage bottlenecks reduce the work your cluster completes.
Ownership, financing and operating capacity matter throughout a long-term programme.
Acceptance, billing, SLAs and remedies should be clear before the cluster is needed.
A delayed cluster can cost more than a quarter. It can put your next model behind schedule.
The fragmented partner: Contract signed on the lowest GPU-hour quote.
Your accountable partner: Energised power and site handover verified.
The fragmented partner: Site power is delayed. The cluster has nowhere to run.
Your accountable partner: Hardware, cooling, fabric and storage planned together.
The fragmented partner: Cooling fails acceptance. Racks remain idle.
Your accountable partner: Cluster tested on your workloads.
The fragmented partner: Fabric is unstable at scale. Training jobs keep restarting.
Your accountable partner: Service begins under agreed acceptance and billing terms.
The fragmented partner: Provider financing falters. Long-term capacity is at risk.
Your accountable partner: Goodput, cluster health and operations tracked continuously.
8,000 GPUs× 720 hours per month× US$3 per GPU-hour
in compute capacity delayed each month
over six months - with your AI roadmap held back too
*Illustrative calculation is the value of delayed capacity, based on an assumed GPU-hour rate and continuous use.
Validate on a pilot block, reserve a dedicated cluster & build an AI factory around your architecture.
Validate your own AI workloads on a pilot block, testing compute throughput, fabric and storage performance before committing to a larger deployment.
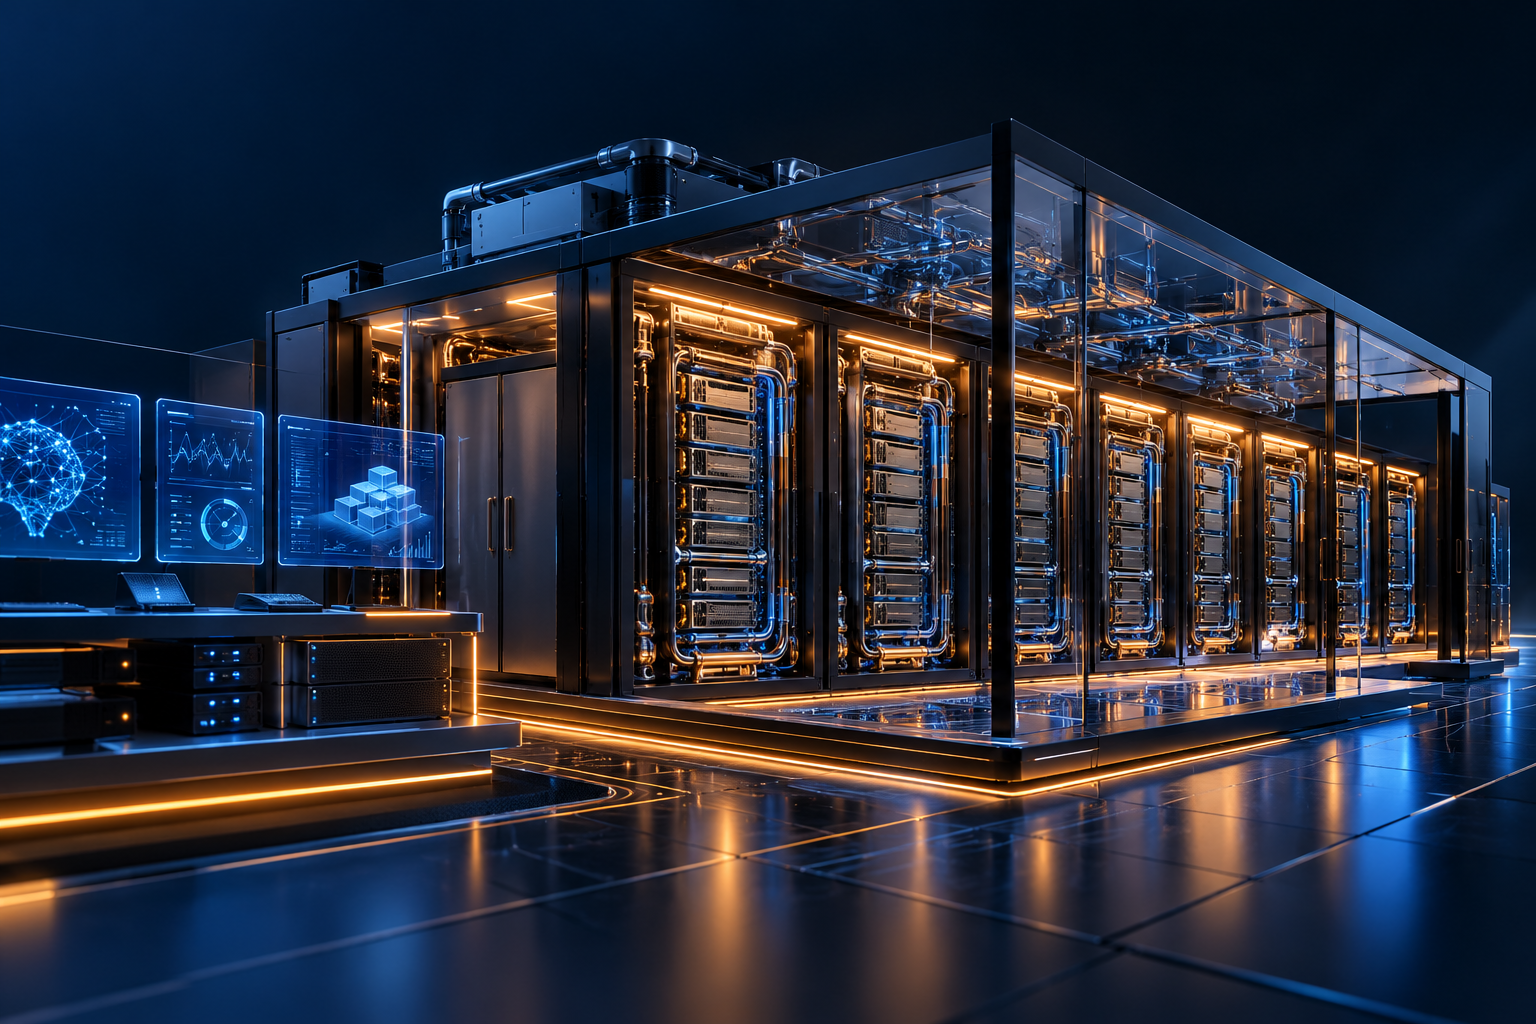
Reserve a single-tenant B300 or GB300-class cluster with bare metal or managed Slurm/Kubernetes, high-performance storage and 24×7 operations.
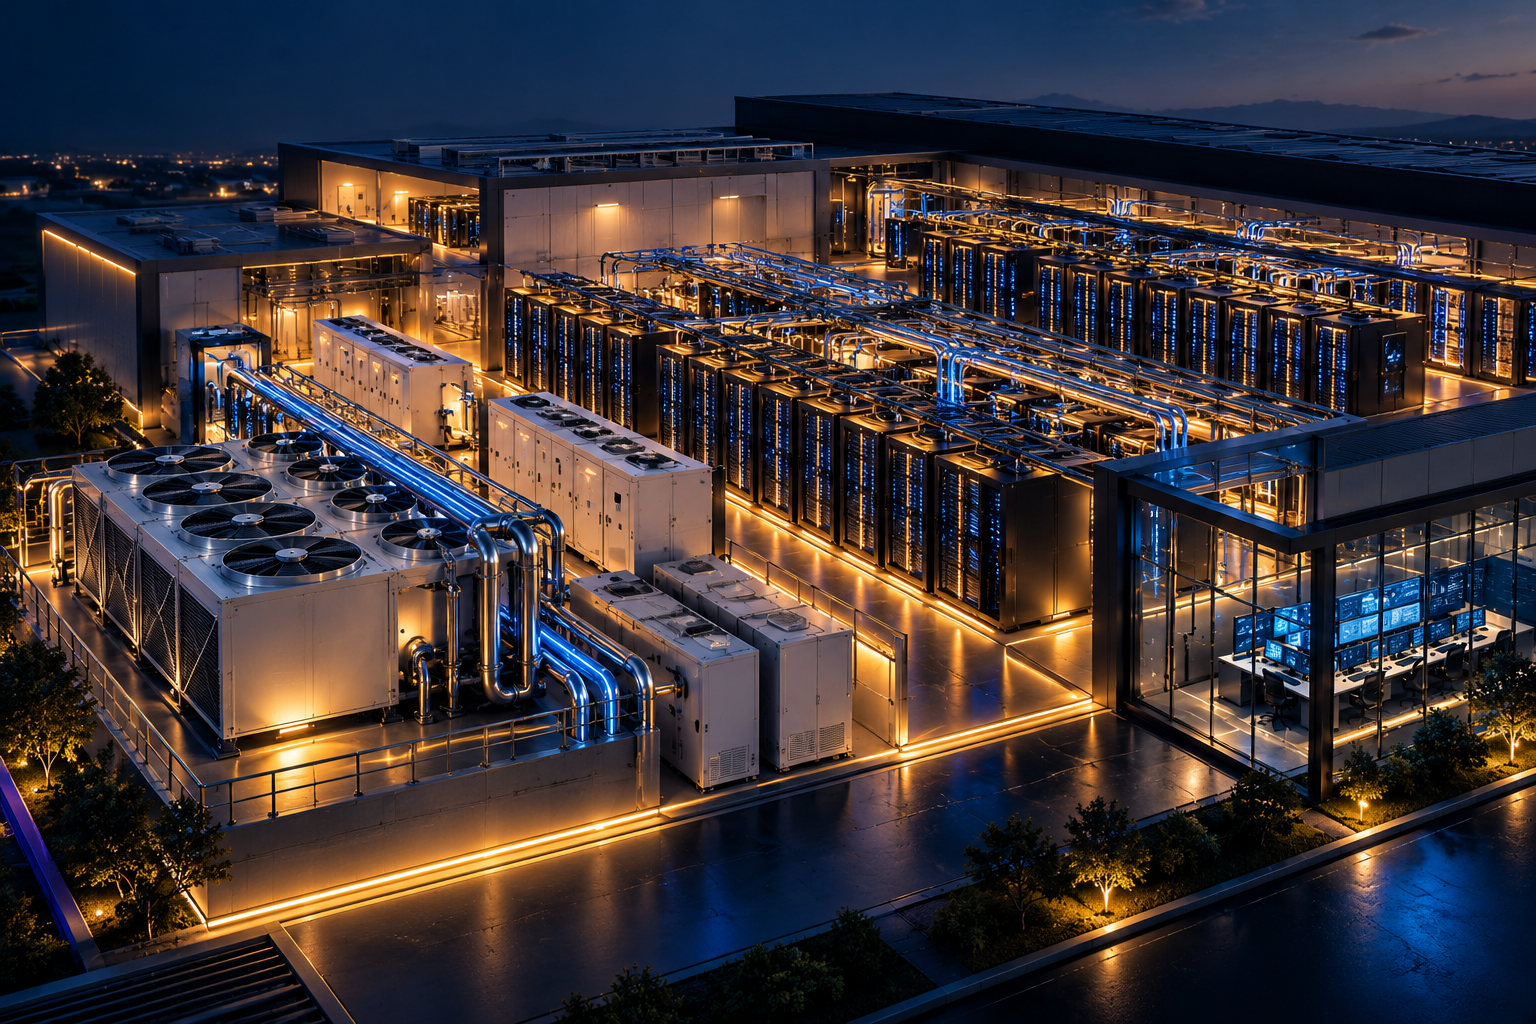
Build an AI factory with site, power, liquid cooling, high-speed fabric, storage and cluster operations engineered around your architecture and expansion plans.
Every layer commissioned, tested and operated through one coordinated plan.
Confirm energised power, cooling capacity and handover dates.
Align GPU, network and storage delivery with site readiness.
Install racks, commission liquid cooling, configure fabric and tune storage.
Complete burn-in, benchmarks and acceptance before declaring the cluster ready.
Run 24×7 operations with cluster health, goodput and spare coverage tracked.
Mission-critical data centre and cloud infrastructure for 2,500+ customers, including 170+ financial institutions.
B300/GB300 programmes spanning power, liquid cooling, fabric, storage and cluster bring-up.
NSE- and BSE-listed, with audited financials and public disclosures.
International AI infrastructure programmes involving 50,000+ GPUs in execution and acquisition.
Data centres, OEMs, GPU clusters, HPC management and 24×7 operations coordinated by ESDS.
Patented infrastructure IP and the sovereign SWARAJ Cloud platform.
Connect with our experts, and we’ll walk you through each answer and the evidence behind it.
We quote only capacity that is energised or has a confirmed handover date in writing, and we share the utility agreement and site power schedule under NDA during diligence.
We disclose the ownership and financing structure of the hardware behind your cluster, so you know exactly which balance sheet stands behind your capacity.
Our contracts set out how your reserved capacity, data and checkpoints are protected and handed back if our own financing changes, so a lender event does not become your outage.
Commissioning is led and owned by our engineering team. Where specialist partners are involved, we name them and remain the single accountable party for the result.
Yes. Burn-in and acceptance run on benchmarks and your own jobs, and billing starts only once the cluster passes the acceptance criteria agreed in the contract.
We align our customer SLAs with our upstream power, network and hardware agreements, so the commitments we make to you are backed by the commitments made to us.
International contracts can be placed under recognised frameworks such as Singapore law with ICC arbitration, where applicable.
Yes. ESDS is listed on NSE and BSE, and our audited financials are publicly disclosed.