6–9 months
Lost to stitching the stack
Drivers, networking, scheduling, storage and model serving can take months to integrate before the first training run.
Give your AI ambitions the infrastructure to deliver. Build and run AI on GPU compute, SWARAJ Cloud, models, enterprise RAG, governance and managed operations in one hosted ecosystem built for production.
Drivers, networking, scheduling, storage and model serving can take months to integrate before the first training run.
Without intelligent scheduling and usage visibility, valuable compute capacity can sit unused.
Prompts, logs, keys and control planes all need to be accounted for when handling regulated Indian data.
Token usage, data egress and currency exposure can make costs harder to forecast as workloads grow.
MLOps, GPU orchestration and AI governance all need expertise to move a use case into production.
An AI partner becomes part of your architecture. Choose poorly, and the consequences can outlast the contract.
Prompts, logs, embeddings and keys may pass through services your team cannot fully inspect or govern.
Provider-specific models, pipelines and tooling can turn a change of vendor into a major engineering project.
Capacity, support and financial stability matter long after the first model goes live.
accountable partner is how you avoid all of it.
Seven layers working together to take enterprise AI into production.
Map your AI workloadsIndian data centres, power and cooling
GPUaaS and dedicated clusters
AI storage and high-speed connectivity
Cloud services and unified management
Pipelines, databases and retrieval
MLOps, LLMOps and model serving
Business-facing AI use cases
From developing a model to governing its use in production, ESDS brings the services around your GPU compute into one connected ecosystem.
AI development and model operations
Models as a service
Vector database and knowledge retrieval
Agent workflows with oversight
Data pipelines and databases
Controls and audit trails
Utilisation and spend visibility
Continuous infrastructure support
Architecture and capability building
Mission-critical data centre and cloud infrastructure for 2,500+ customers, including 170+ financial institutions.
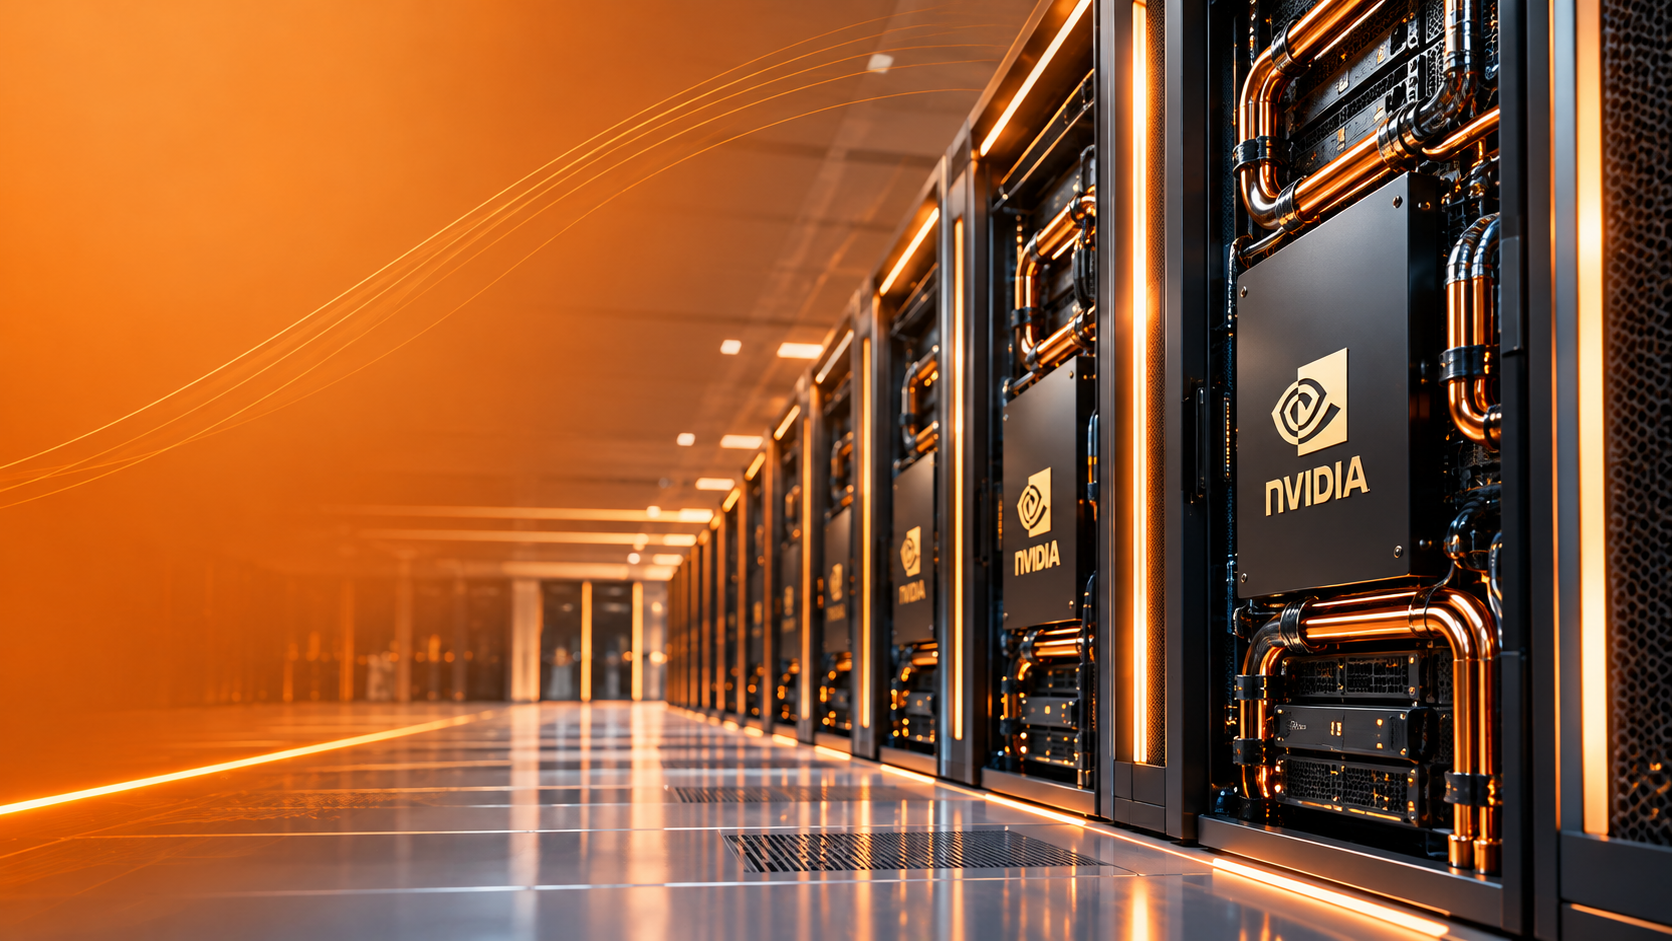
B300/GB300 programmes spanning power, liquid cooling, fabric, storage and cluster bring-up.

International AI infrastructure programmes involving 50,000+ GPUs in execution and acquisition.
NSE- and BSE-listed, with audited financials and public disclosures.
Data centres, OEMs, GPU clusters, HPC management and 24×7 operations coordinated by ESDS.
Patented infrastructure IP and the sovereign SWARAJ Cloud platform.
Bring your first AI use case to life on a connected ecosystem that can grow into a fully managed AI Factory.
Launch your use case on SWARAJ Cloud with GPU compute, models, enterprise RAG and MLOps in one connected environment.
Secure single-tenant GPU capacity for fine-tuning and production inference, with networking, storage and operations engineered around your workload.
Put the complete seven-layer stack to work under one accountable operating model, with governance, cost visibility and 24×7 managed operations.